Cloud service cost chart with breakdown by category

Spend audit and resource tagging

Cloud instance costs: where the budget leaks away

Review of oversized and forgotten shut-down resources

A cloud bill almost never goes up because of a single decision. It goes up through accumulation: an instance that kept double the CPU "just in case," a volume nobody detached when the machine using it was deleted, a test environment that was spun up on a Friday and kept running for three months. None of those line items is dramatic on its own. Together, they explain much of the spend that cannot be attributed to any specific team.

Before touching any numbers, it is worth looking at the breakdown by service and by tag. If half of the resources have no team, project, or environment tag, the problem is not the price: it is that there is no way to know who consumes what. Tagging is not bureaucracy, it is the precondition for any serious review.

The second pattern that appears in almost all active accounts is usage commitments signed without measuring actual demand. A reserved discount only pays off if the load is stable and sustained. When it is signed based on peaks that have already passed, the commitment is still paid even if the instance sits idle.

Regular review works better as a habit than as a one-off project: look at the services with the highest spend, confirm they are still in use, and turn off what is no longer needed. It does not promise magical savings, but it keeps spending aligned with what is actually consumed.

Cloud instance costs: where the budget leaks

Buckingham Cloud doesn't sign off with faces or invented job titles. What's behind it is a team of platform engineers and SREs who work on clusters, infrastructure templates, and production dashboards every day. We write about what we had to debug, not what sounds good in a proposal.

Writing

Field notes, not manuals

Every entry about instance costs, resource limits, or remote backend comes from a real review: which service was overconsuming, which tag was missing, which disk was left orphaned after a shutdown. We publish the configuration snippet and the dashboard that shows it, even if the result isn't elegant.

Technical review

Before publishing, someone breaks it

No text goes up without someone else on the team trying to reproduce the scenario. If a tool comparison doesn't hold up with our own data, it's marked as an observation and not as a recommendation. We'd rather say "this worked for us in this context" than sell a universal solution.

Independence

No sponsorship, no vendor bias

We do not accept agreements with cloud providers or with vendors of observability tools. When we mention a service, it is because we use it or ruled it out for specific reasons. That is the only reason the log remains useful for teams that need to decide, not read marketing.

Editorial contact

Corrections and missing topics

If you find an error in a configuration snippet or want to propose a topic for the next entry, write to us. We read everything that comes in and, when the case warrants it, we turn it into an article with the full context. The email address and phone number are on the contact page.

Want to follow the next entries on costs, queues, and deployments?

Write to us or join the weekly newsletter
Cloud service cost chart with breakdown by category

Cloud instance costs: where the budget leaks away

Review of oversized and forgotten shut-down resources

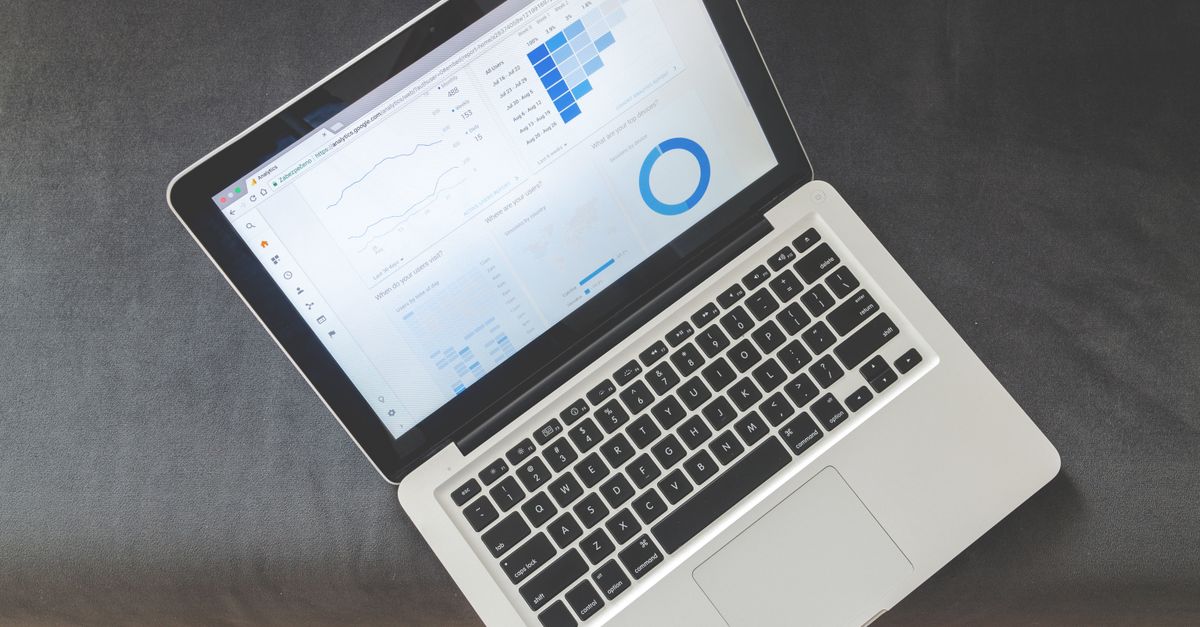
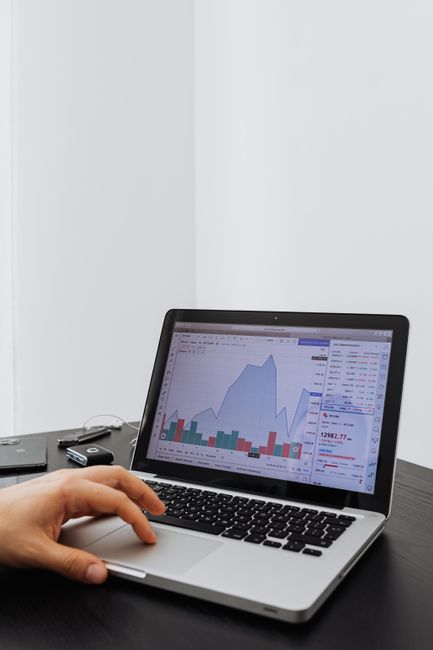
These screenshots accompany the spend audit we describe in the post: they help identify the type of dashboard, the breakdown, and the labeling that should be reviewed each month. They are reference images, not from an account of our own.

Cloud service cost chart with breakdown by category
Breakdown by category

The line item that grows is not always the one that is used the most

A billing dashboard grouped by service shows at a glance which family of resources takes the largest share of monthly spend.

Screen with configuration files and a highlighted change plan
Resource labeling

Without consistent tags there is no possible attribution

When each team invents its own keys, the cost report by area becomes a manual exercise that no one sustains over time.

Monitoring dashboard with metric charts and event logs
Actual usage versus size

Large instances with CPU nearly idle

Comparing measured usage with the contracted size often exposes oversized resources that no one has reviewed since the day of deployment.

Flow diagram between producers and consumers in a queue
Test environments

Staging clusters that are still running

Temporary environments that are spun up for a test and never shut down are one of the most common leaks in active accounts.

Containers and services deployed in a cluster with startup logs
Usage commitments

Reserved commitments made without measuring demand

A usage commitment signed for a one-off peak can end up paying for capacity the service no longer needs.

This post about cloud instance costs is signed by the Buckingham Cloud editorial team, the same group of engineers who document what they see in production and not what the brochures promise. There is no external figure behind the text: we write about what we review in our own accounts and in those of the teams we work with.

When we talk about oversized instances, orphaned disks, or test environments that nobody shuts down, we do so from the practice of auditing invoices month after month and of arguing with platform teams about why a resource is still running. We do not sell tools or charge for recommending providers. If we have not tested something, we say so.

The specific figures for each account change; what stays the same is the habit of reviewing. If you want to raise a specific case, write to us at hello@buckinghamcloud.com or call us at +54 11 4281-7054.

Cookie settings

We use cookies to keep the site stable, remember basic options, and understand which pages are useful. You can accept, reject, or review the settings before continuing.